

- Speech: recognition, synthesis, speech-to-text translation, and spoken chat
- Images: captioning and visual question answering, asked in text or by voice, answered in text or speech
- Video: questions about a clip, using the frames alone or the frames and their soundtrack
- Audio understanding: open-ended and multiple-choice questions about a recording
- Tool calling: function calls from an image and a spoken request
- Output control: let the model choose its output modality, or force text, speech, or interleaved output
Setup
Install Transformers and the packages used by the examples.torchcodec decodes video and the soundtrack of a video. A GPU is recommended; the model runs in bfloat16.
processor.audio_tokenizer), which turns generated speech codes into a 24 kHz waveform.
Helper
Every example below is a chat conversation. The helper renders it, loading any image, video, or audio it names, then generates and returns the text reply and the speech, if any. The model chooses its output modality itself, guided by the system prompt. Passgeneration_mode="text", "audio", or "interleaved" to force one.
Text output is greedy. Speech uses audio_temperature=0.4, audio_repetition_penalty=1.2, and audio_repetition_window=64. These are also the defaults in the model’s generation_config.json; the helper passes them explicitly to keep the examples reproducible.
Speech
Text-to-speech
Use the system promptPerform TTS in {language} using a {female|male} voice. and pass generation_mode="audio". For English, say American English or British English. Supported languages: English (American and British), Arabic, Chinese, Danish, Dutch, Finnish, French, German, Greek, Hebrew, Italian, Japanese, Korean, Polish, Portuguese, Spanish, Swedish, and Turkish.
Speech recognition
Use the system promptPerform ASR in {language}. Pass audio in the user turn as {"type": "audio", "audio": <path or URL>}. It’s resampled to 16 kHz mono on load.
Speech translation
LFM3-Omni translates speech into text. Translation works best into or out of English. Name the source and target languages in the system prompt, for exampleConvert the speech in {source} to written {target}. or Please translate the following spoken {source} into {target} text. The model was trained on many phrasings, so pick the one that works best for your data.
Spoken chat
Use the system promptRespond with interleaved text and audio. The model answers with text and speech interleaved, so speech can start playing before the full answer is written. The question can be text or speech. Keep the system prompt exactly as shown, and give any further instructions in the user turn.
reply.wav)
Respond with text.
Images
Images are processed at their native resolution. Recommended system prompts:Describe the provided image. for captions, and Answer questions about the provided image. Base every answer only on what can be seen. for questions.
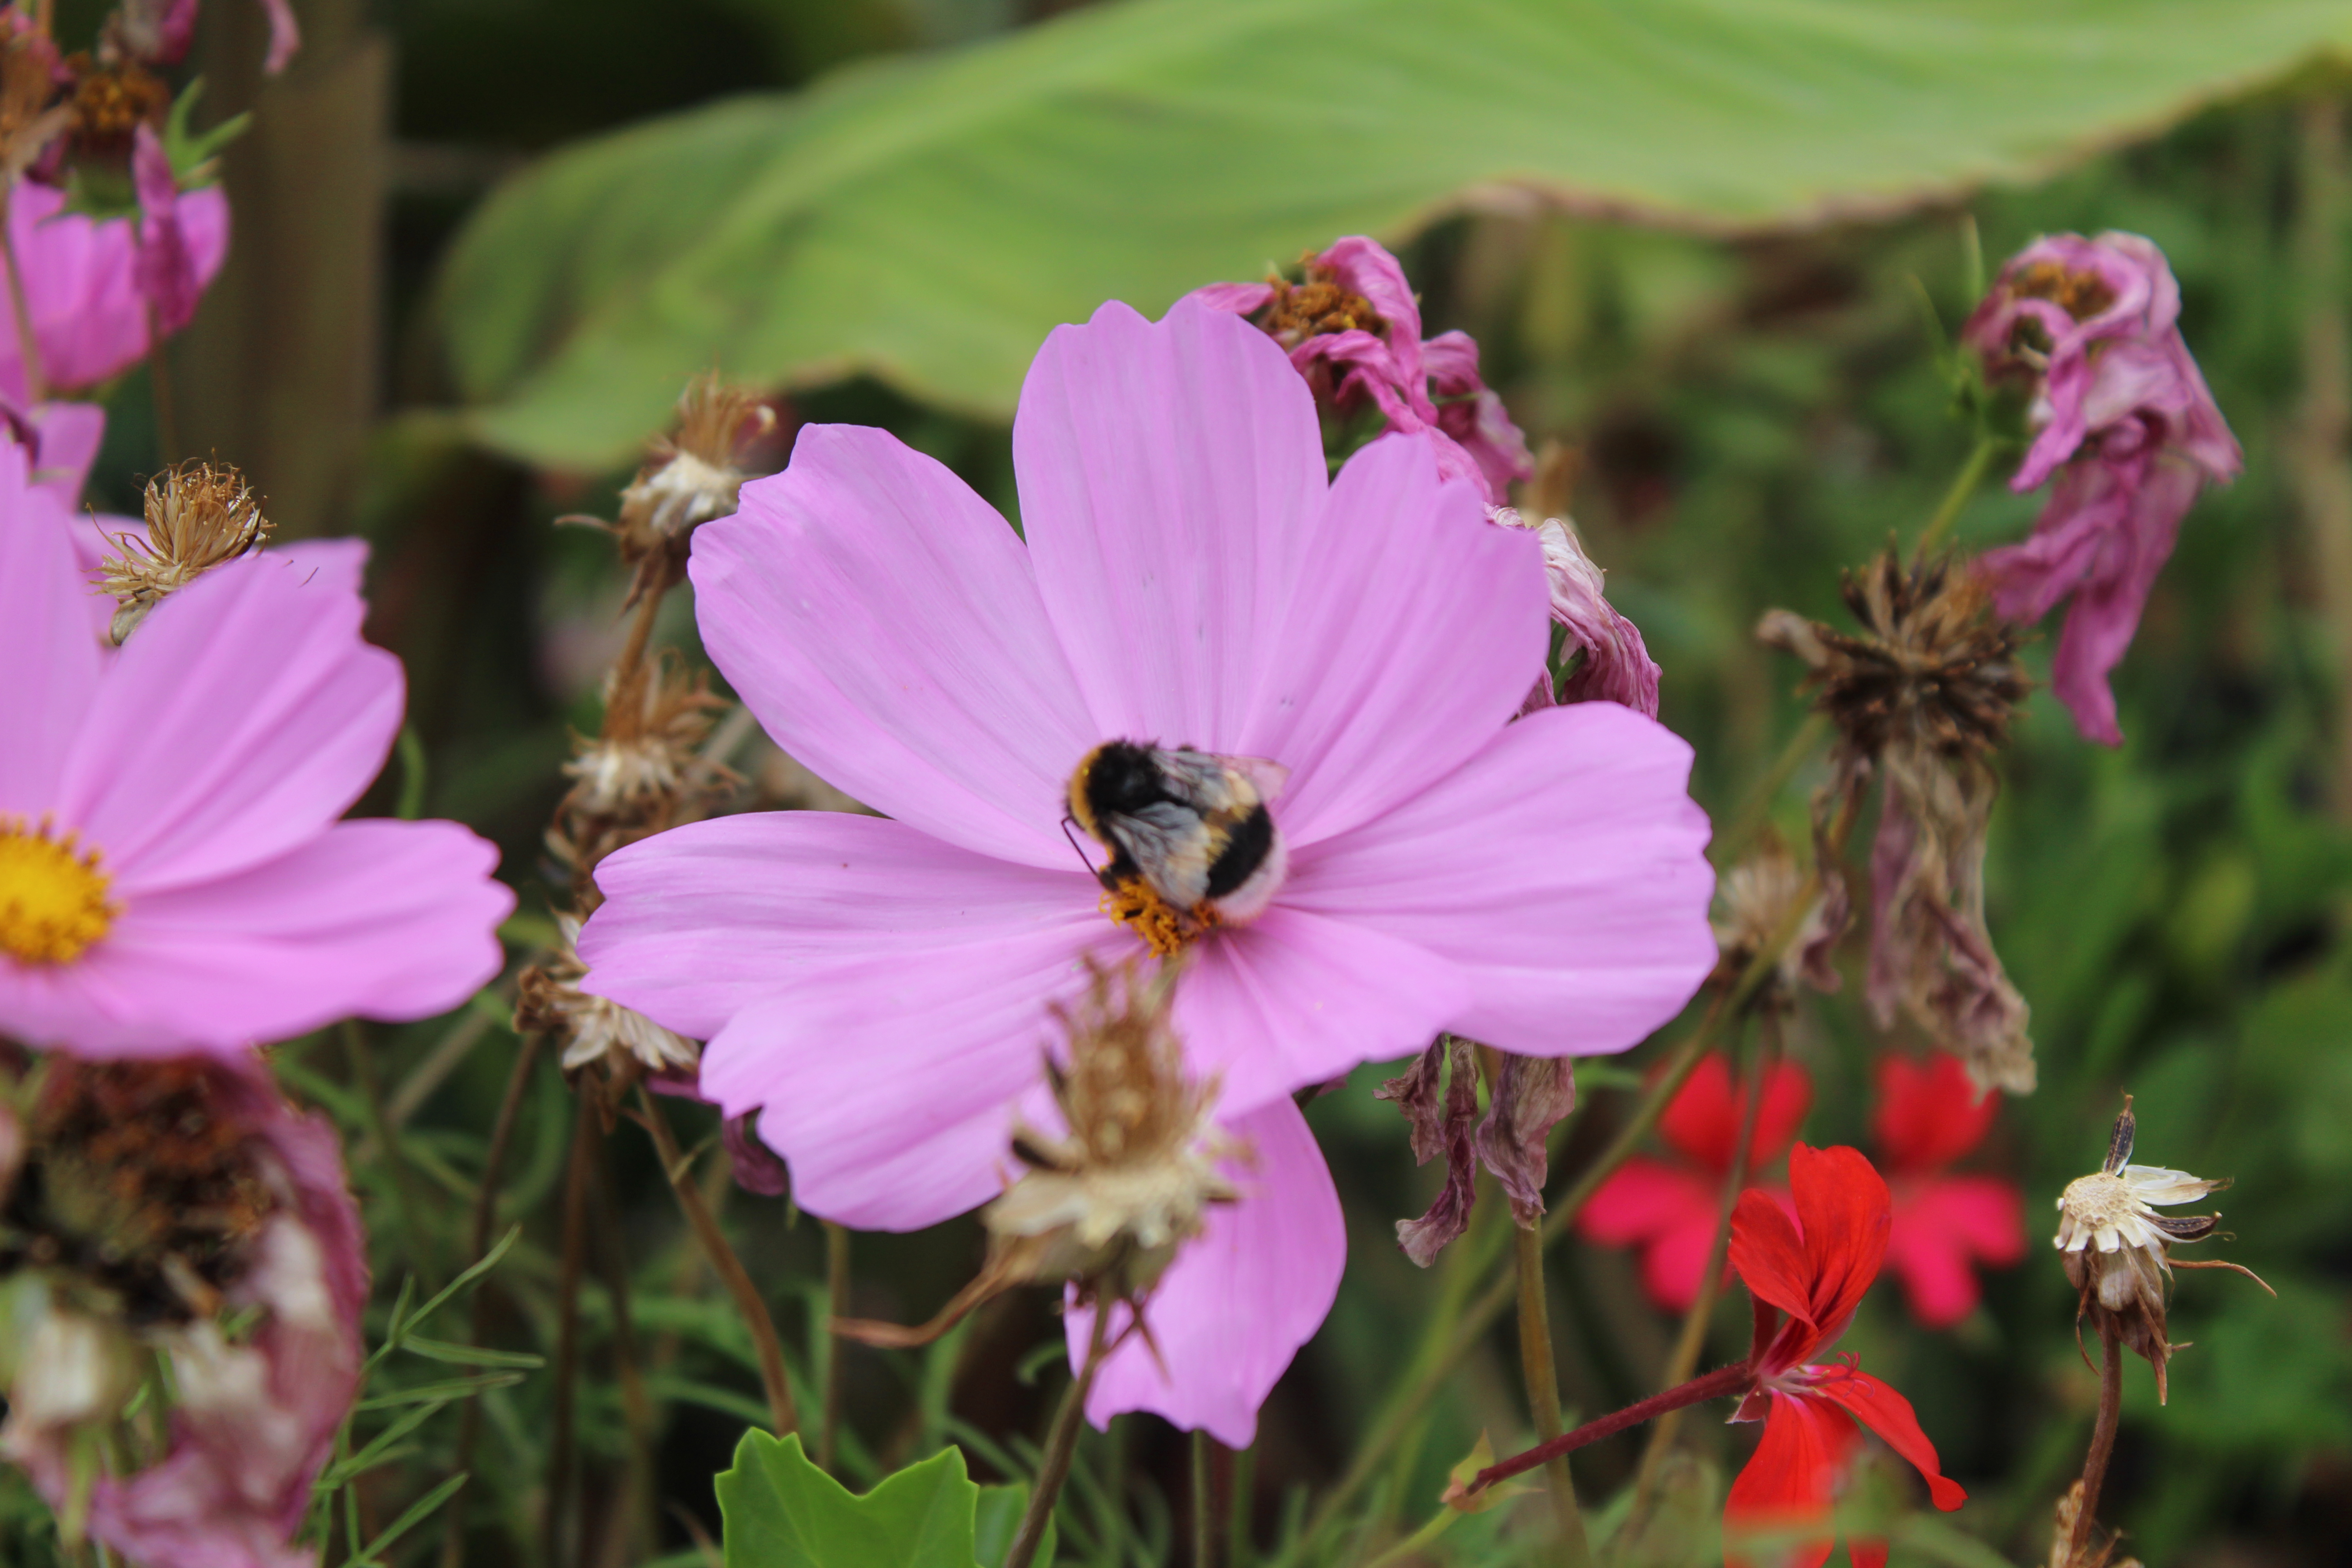
Respond with text.
bee_answer.wav)
Video
Video is sampled at 2 frames per second. Consecutive frames are paired, and each pair is prefixed with its timestamp. Use the system promptAnswer questions about the video using what you see and hear.
To include the soundtrack, pass load_audio_from_video=True and use_audio_in_video=True. The processor reads the video’s audio track and interleaves it with the frames, so each pair of frames is followed by the sound that goes with it.
Audio understanding
Open-ended questions about sounds, music, and speech need no system prompt: put the audio and the question in the user turn.Answer questions about the provided audio clip. Base every answer only on what can be heard. and end the user turn with Please choose the answer from the options.
Tool calling
This example shows the model a restaurant photo and asks by voice to book a table. The model reads the restaurant name from the sign and combines it with the city, date, time, party size, and reservation name from the spoken request. The example only prints the proposed call and doesn’t make a reservation. Pass thebook_table schema to apply_chat_template() with tools=.... The model returns the call between <tool_call> and </tool_call>.
 Photo: Café de Flore, Paris by ayustety, CC BY-SA 2.0.
tool message. See Tool Use for the full workflow.
Output modality
generation_mode overrides the output modality the model would choose on its own. Use generation_mode="audio" (speech only) for reading text aloud. For open-ended answers, prefer "interleaved". This example answers the same question in text and in interleaved text and speech: